The Future is the Label.
Peer-reviewed research. Live benchmark wins. Government-cleared.
Recognized by
 TMLR
 The AtlanticTIME
EigenLabs: One GPU Beat the Frontier at Forecasting
Ben joins EigenLabs’ PostAGI podcast to discuss training AI on real-world outcomes to beat frontier models at forecasting with a single GPU.
Awarded grants totaling $1.6M from Coefficient Giving and Longview Philanthropy
The grants will scale and harden our Foresight AI forecasters for high-stakes decisions and support the development of Model Factory: our platform that turns messy data into standardized RL environments for model training.


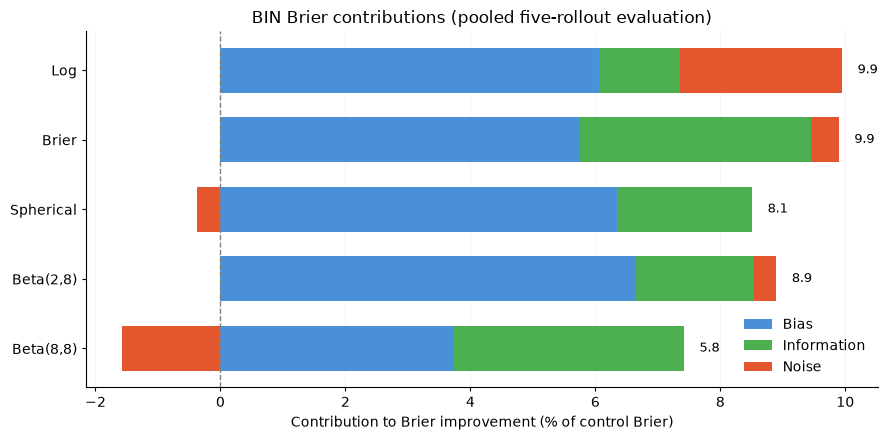
How Proper Scoring Rules Shape LLM Forecasting
Research with Philip Tetlock and Ville Satopää shows how training rewards shape AI forecasting accuracy, calibration, and behavior.
CoreWeave: Teaching AI to Make Predictions
Ben joins CoreWeave’s Ritu Jyoti to discuss turning messy business data into models that predict what happens next.
Watch the conversation →
Foresight v4 sets the Pareto frontier for AI forecasting
We released Foresight v4: a new generation of forecasting models that push the accuracy-cost frontier, with low-cost and full-strength configurations for production forecasting agents.
Foresight v3 reaches superforecaster range on ForecastBench
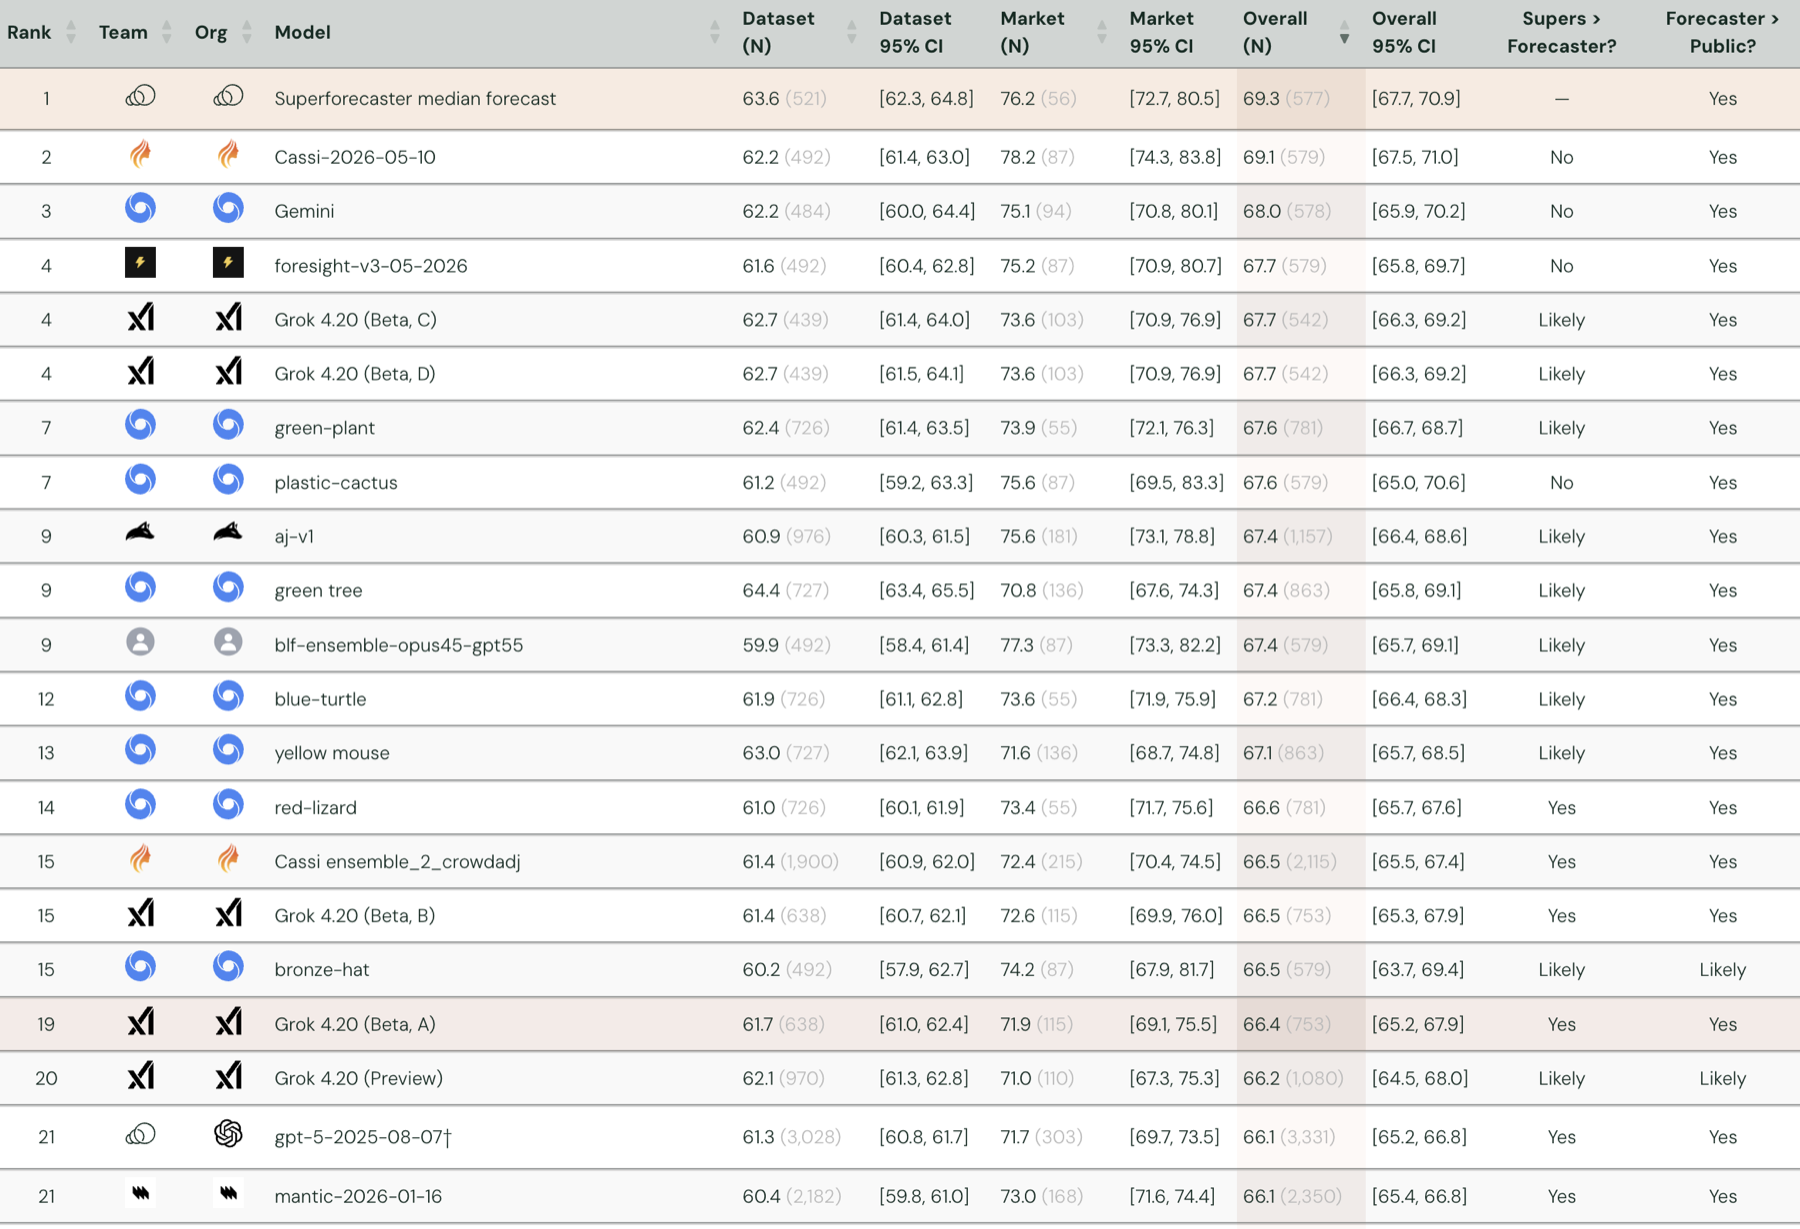
Foresight v3 scores within range of the superforecaster median on ForecastBench, with no statistical superforecaster edge. Foresight v3 beats every other frontier AI entry from OpenAI, Anthropic, and xAI, with only Gemini marginally ahead—while running on a single GPU.
Future-as-Label earns spotlight in AI Forecasting @ ICML
Future-as-Label, our core proprietary methodology for training AI from real-world outcomes, was selected as one of ten spotlights at the ICML 2026 Workshop on AI Forecasting.
Training Large Language Models to Predict Clinical Events
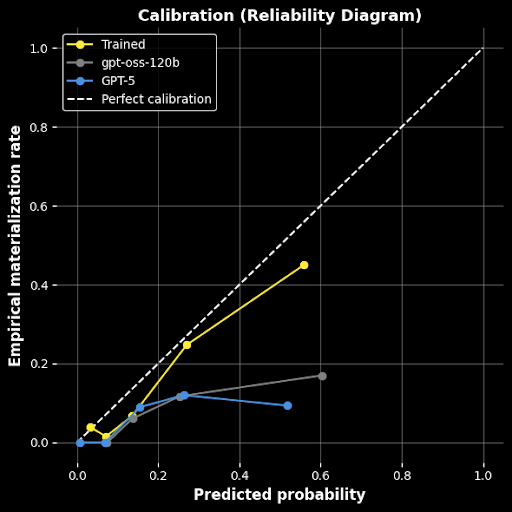
Foresight Learning trains AI to predict clinical events directly from raw clinical notes, with no hand-labeled dataset. It learns from outcomes that appear later in the patient record, letting hospitals build calibrated predictors for their own patient populations. On MIMIC-III, our GPT-OSS-120B model cut calibration error by about 70% and slightly beat GPT-5 on Brier score.

Forecasting supply chain disruptions with foresight learning
Foresight learning trains LLMs to generate calibrated probability forecasts of rare supply chain disruptions, outperforming GPT-5 in accuracy, calibration, and precision — with structured probabilistic reasoning emerging from training alone.
Foresight-v3 becomes the #1 AI forecaster
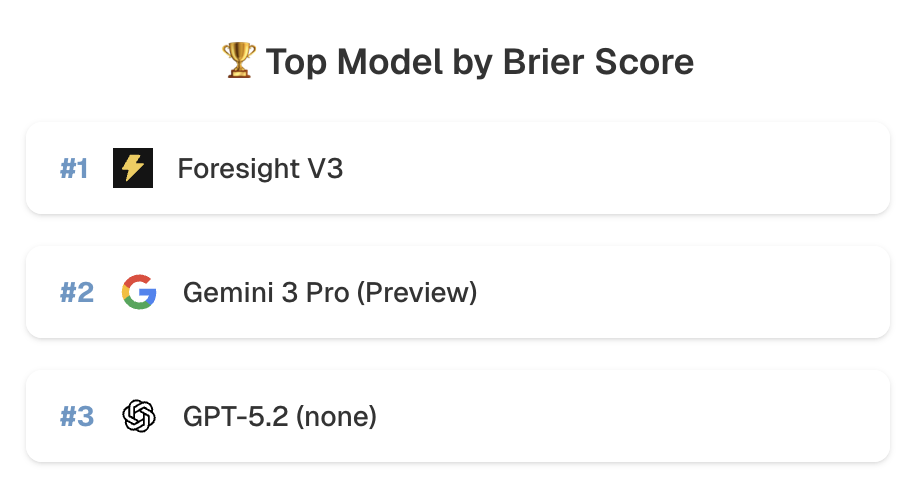
Foresight-v3 ranks first overall on ProphetArena — an independent AI forecasting benchmark from UChicago — by Brier score, outperforming GPT-5, Gemini 3 Pro, and every frontier model. Also #1 in Sports.
#1 on ProphetArena Sports
Foresight-32B beats every other model at predicting sports outcomes on ProphetArena, a live prediction market leaderboard — with 105.9% Market Return, ahead of GPT-5.2, Minimax M2, Gemini 3 Pro, and Qwen3-235B.
Foresight-32B outperforms frontier models on ForecastBench
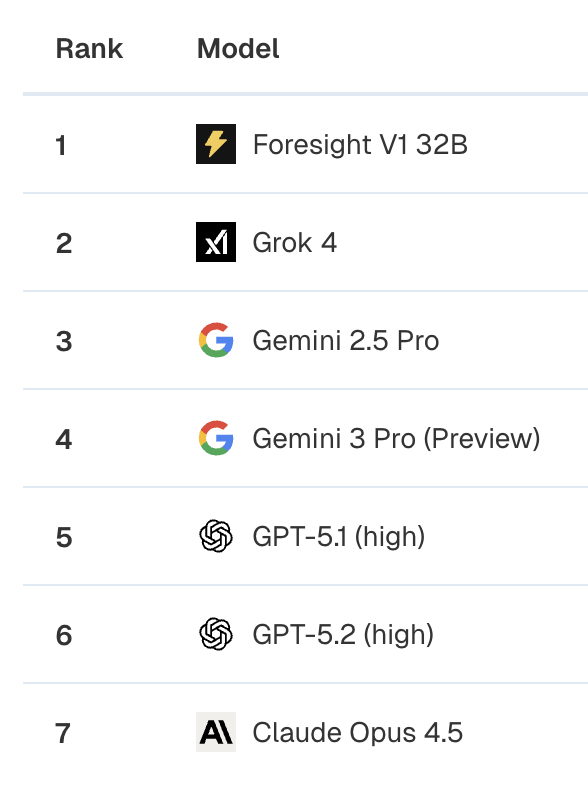
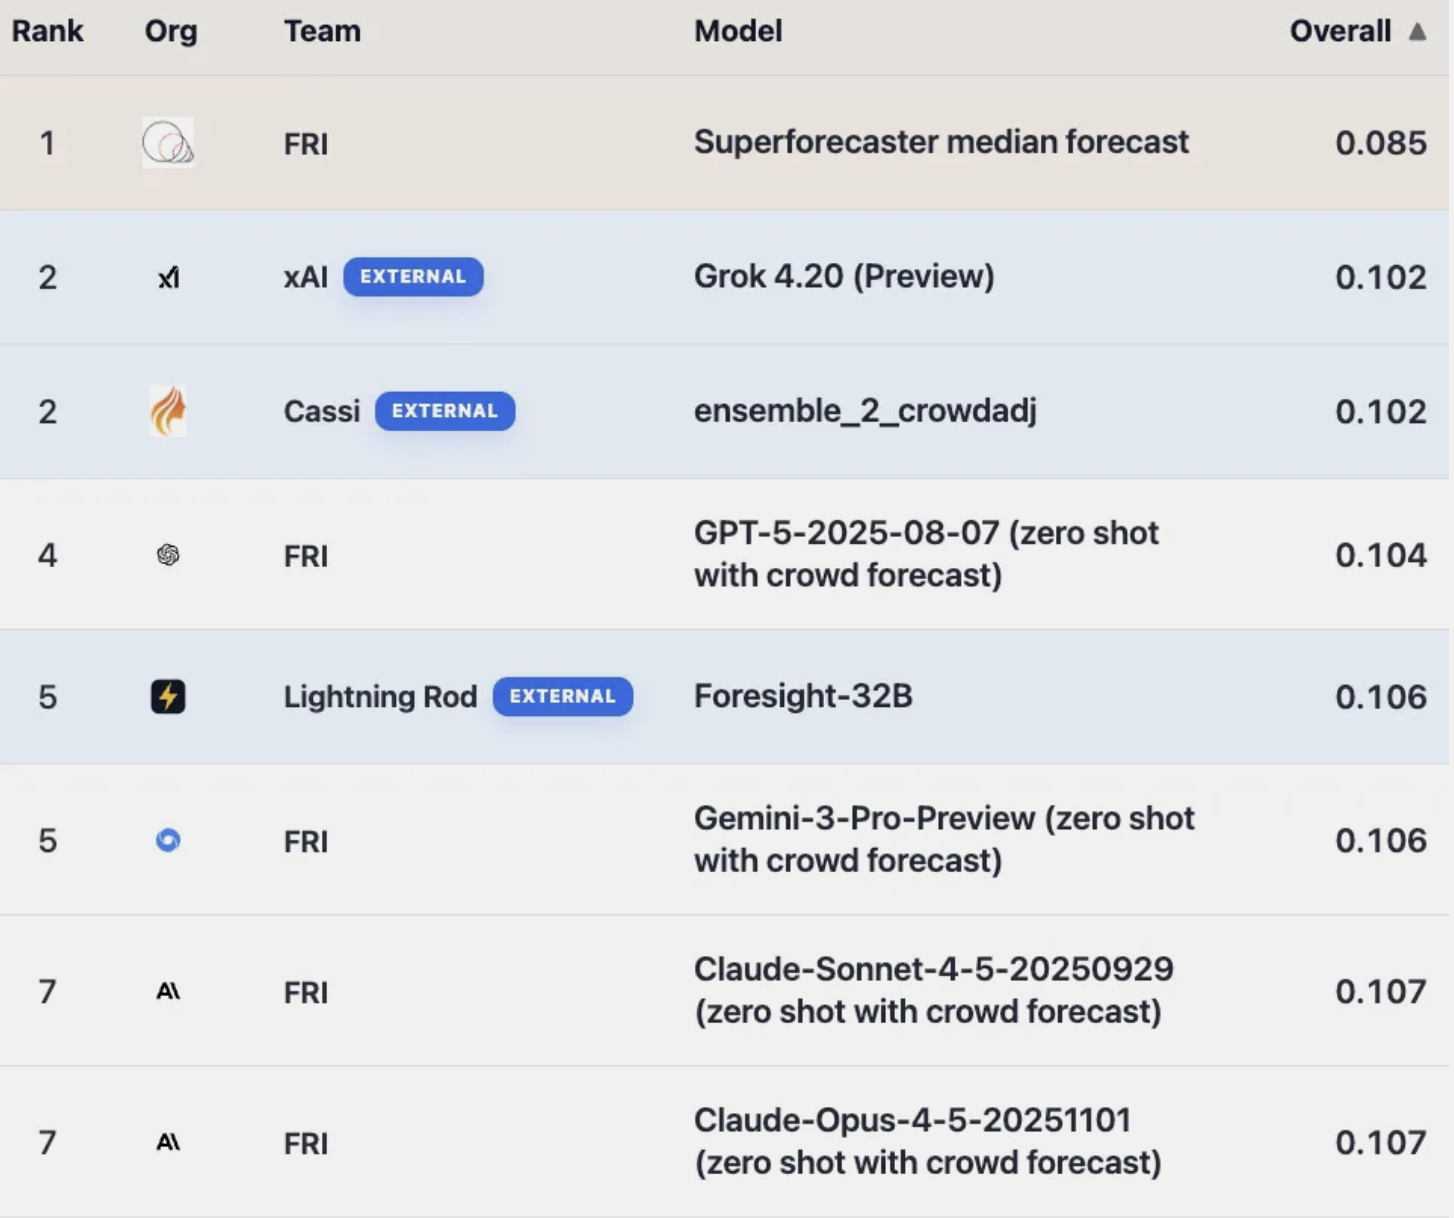
Top 5 on the ForecastBench tournament, outperforming Gemini 3 Pro, Claude Sonnet 4.5, and o3.
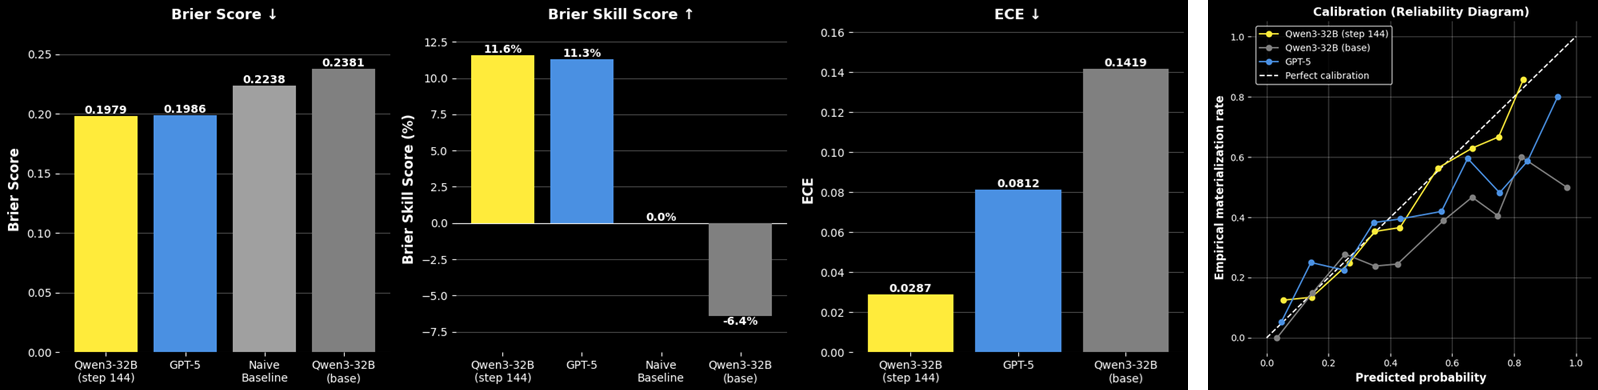
Foresight-tuned 32B model outperforms GPT-5 at predicting public company risks
Foresight learning on raw SEC filings trains a 32B parameter model to beat GPT-5 in accuracy & calibration at predicting public company risks. Deployable on a single GPU for maximum data privacy.
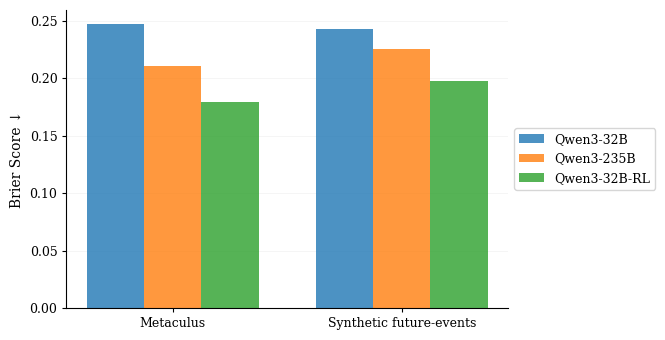
Future-as-Label enables scalable RL
We show that AI can learn directly from real-world outcomes at unlimited scale, no human annotation required. The future itself becomes the training signal. Improved Brier scores 27% and halved calibration error, outperforming Qwen3-235B with a 32B model.
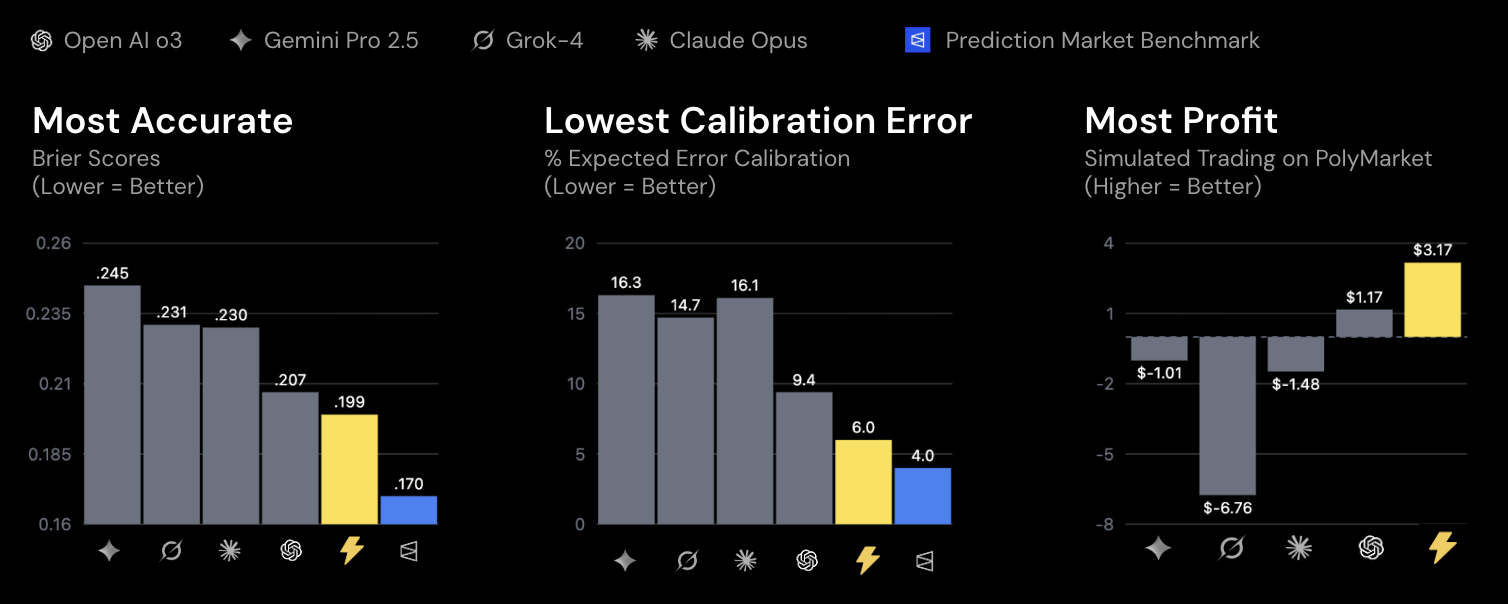
Foresight-32B beats frontier LLMs on live Polymarket predictions
On live Polymarket data, Foresight-32B defeated models 100x larger across every key metric — Brier score, calibration error, and simulated trading profit.
Defense & DARPA awardable
Vetted and approved for immediate defense procurement. Government agencies can access our technology directly via the ERIS and CDAO Tradewinds federal innovation marketplaces.
Published in TMLR: Outcome-based RL achieves frontier accuracy with a 14B model
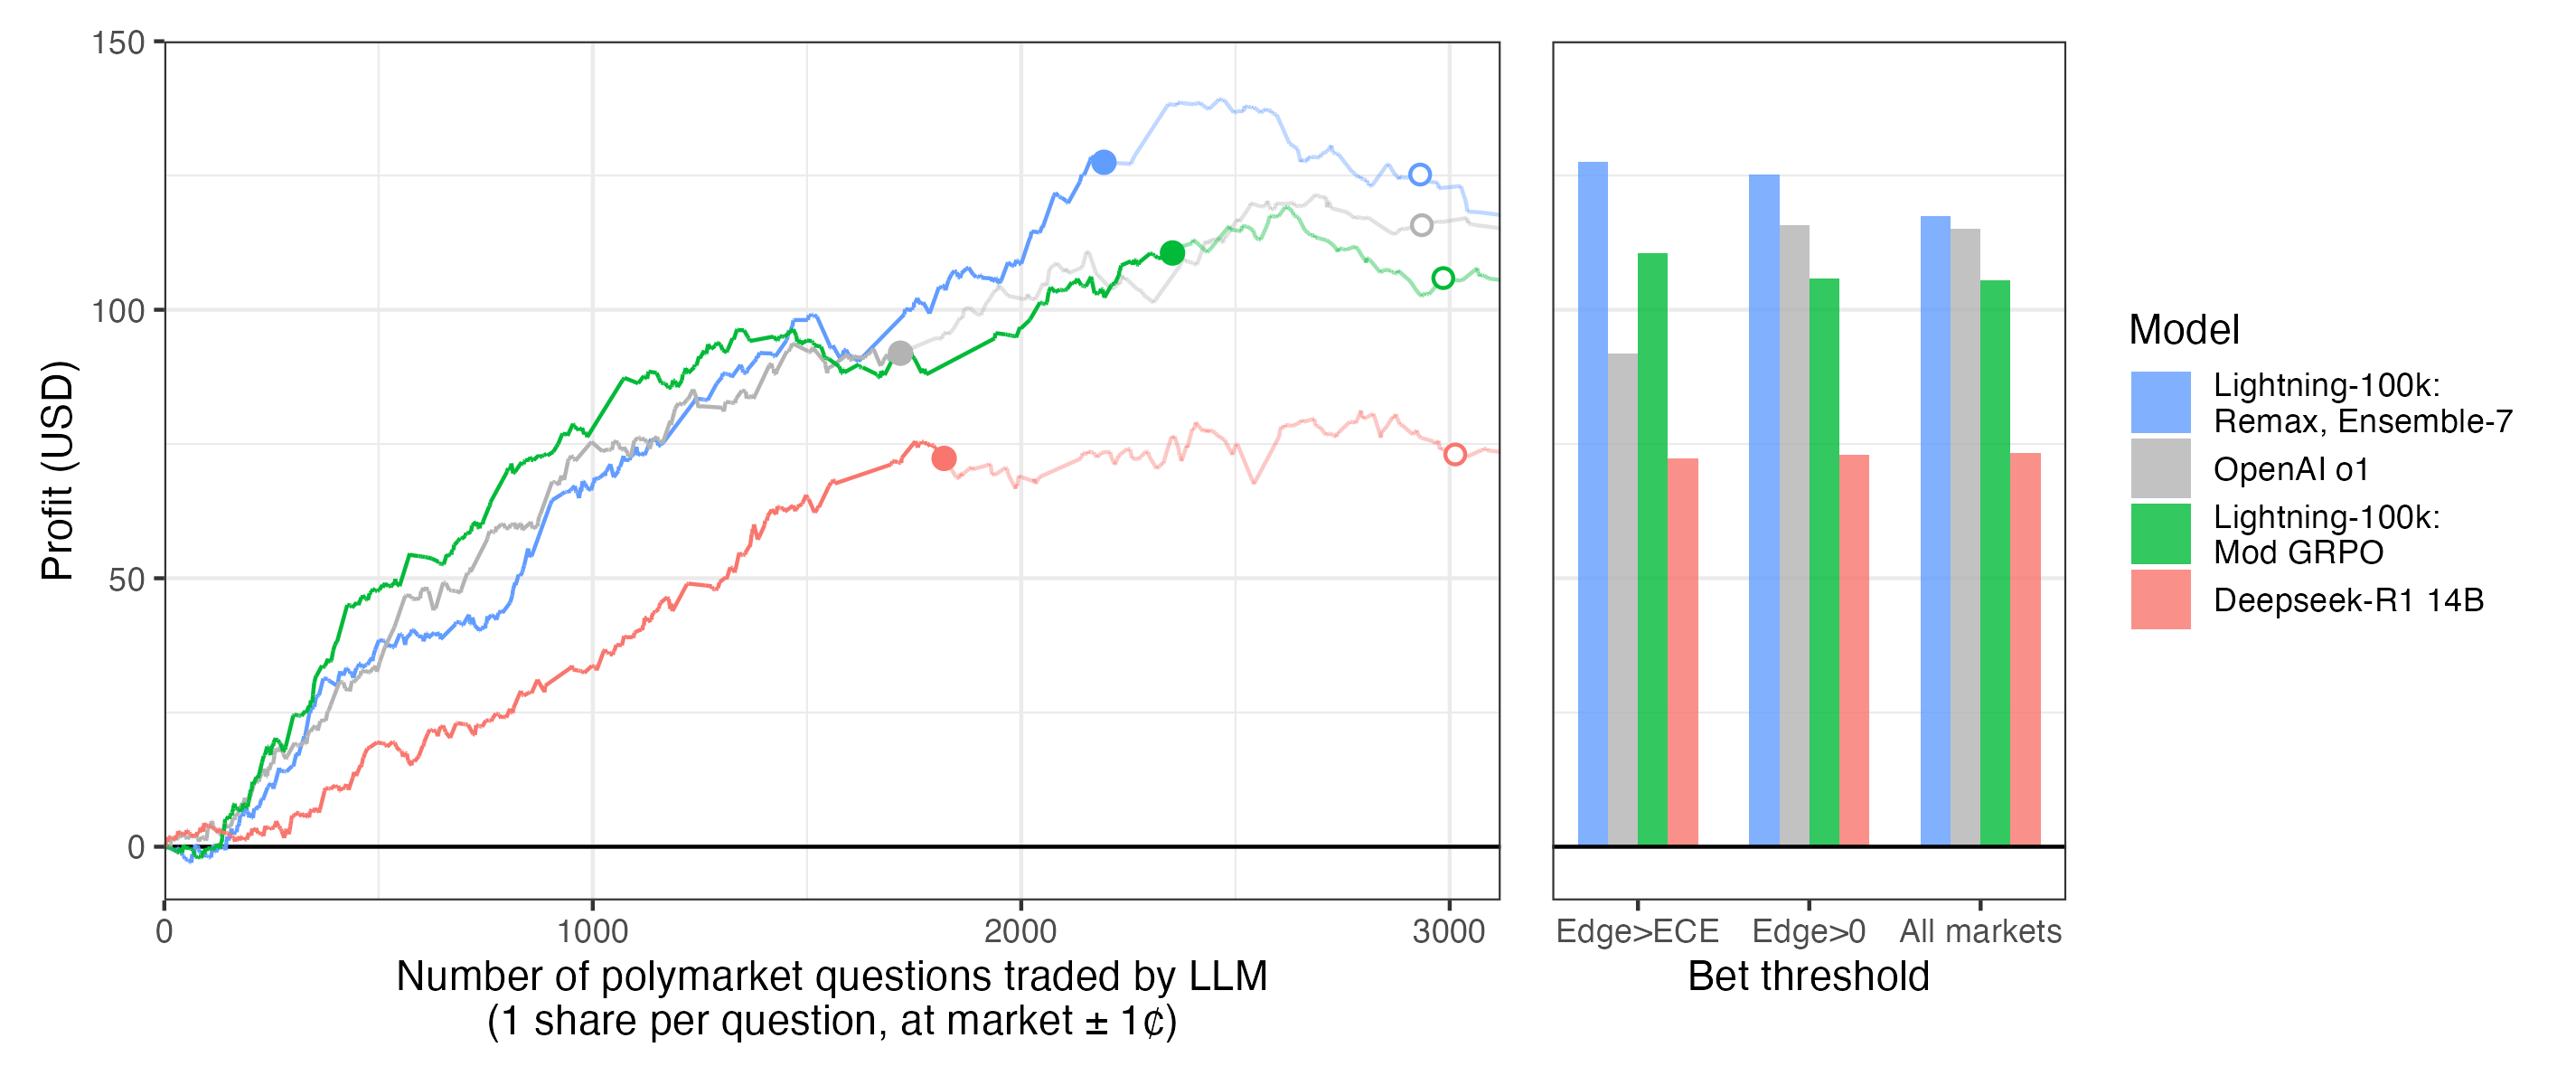
Our 14B model matches OpenAI o1 in predictive accuracy and generates >10% profit in live trading simulations — published in Transactions on Machine Learning Research.
LLMs can teach themselves to predict the future
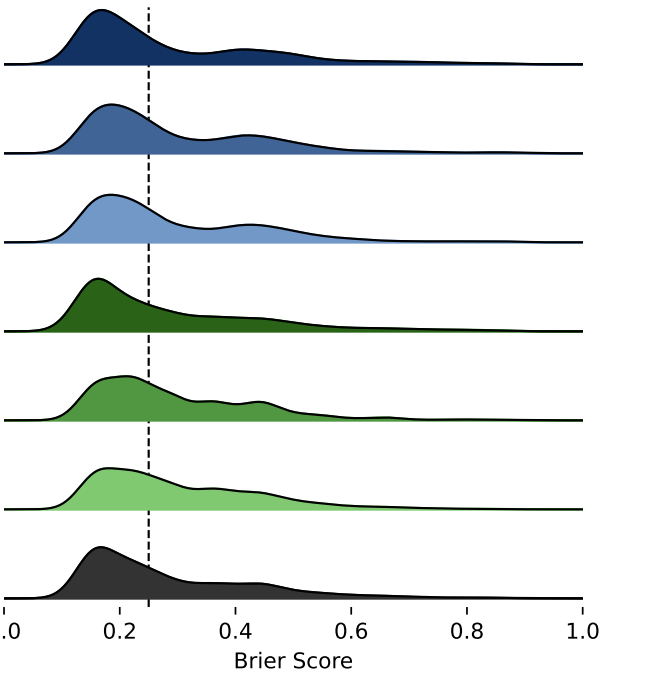
Self-play and DPO yield 7–10% accuracy improvements on Phi-4 14B and DeepSeek-R1 14B — bringing smaller models to frontier-level forecasting performance without any human-annotated training data.
Our Founder
Ben Turtel